01 — Retrieval · Italian
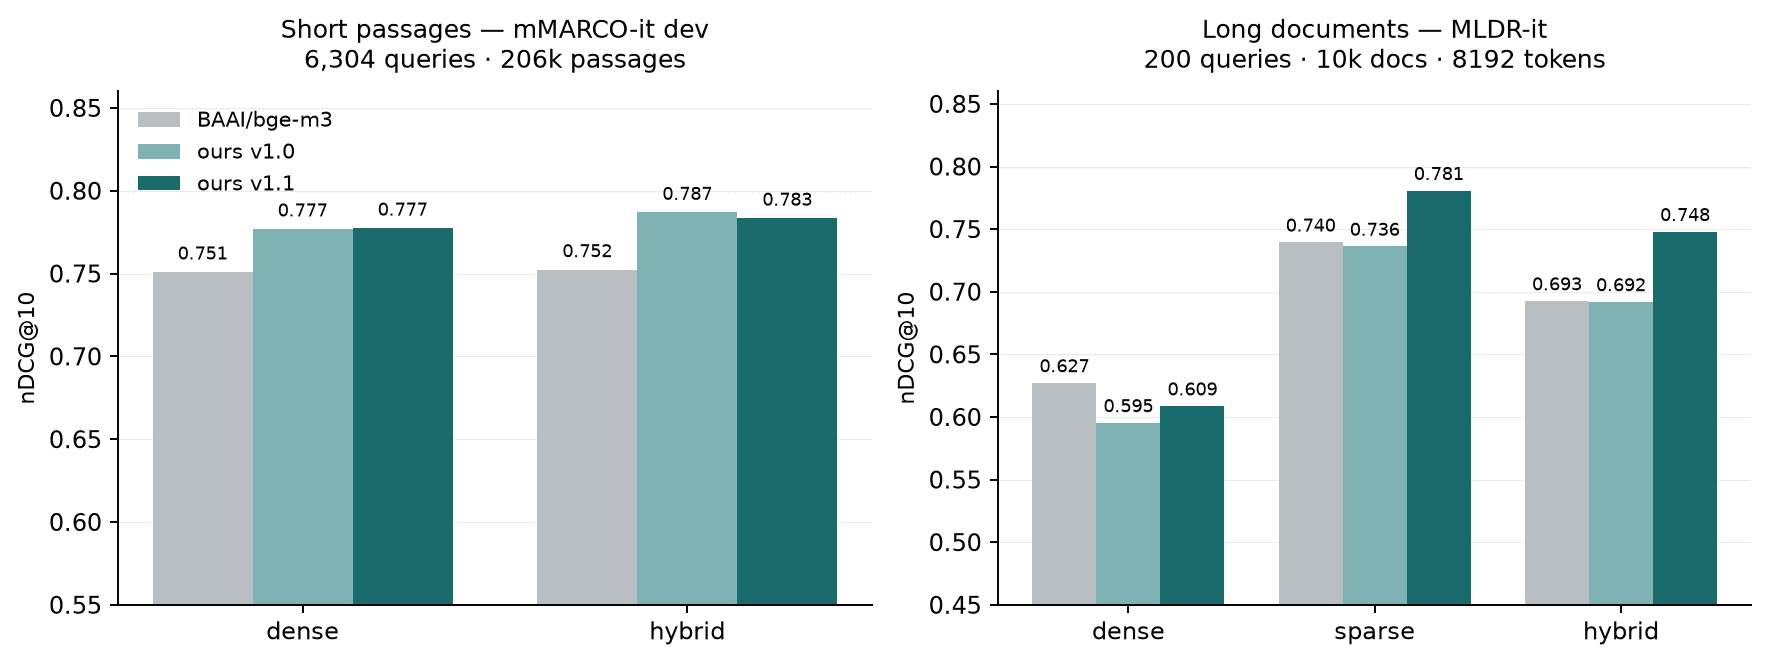
+0.055
nDCG@10 over bge-m3 — long documents, hybrid
bge-m3-italian
Italian retrieval fine-tuned from bge-m3 — a drop-in replacement that beats the base model in hybrid search.
Same 1024 dimensions, same 8192-token context, all three heads — dense, sparse and ColBERT — trained and shipped, so it replaces bge-m3 without changing a line of code. Measured against the base with identical code and a 10,000-sample paired bootstrap on mMARCO-it and MLDR-it; registered on MTEB; ONNX fp32 and int8 builds for Text Embeddings Inference and fastembed, checked against the PyTorch weights.
dense + sparse + ColBERT · mMARCO-it · MLDR-it · MTEB · ONNX fp32 / int8 · right answer at #1: 62.5% → 66%
sentence-transformers · bge-m3 · FlagEmbedding · ONNX
Hugging Face ↗562 downloads